Key takeaways
- Tool safety is a decision problem, not a prose refusal problem.
- Optimise for false negatives on irreversible actions.
- Never test destructive gates against production.
Why this matters
Coding harnesses learned the hard way that agents will cheerfully run dangerous commands when persuaded. LangChain’s Auto Mode narrative argues that cheap classifiers make the same pattern available to every agent runtime.
Reference policy
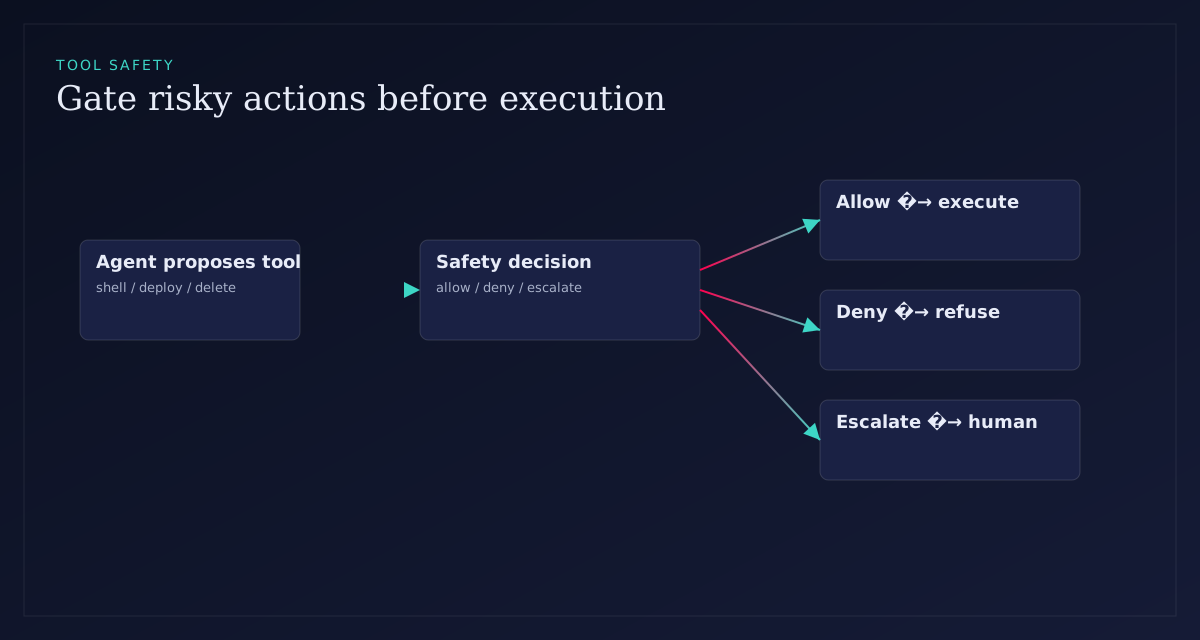
- Classify tool name + args + recent trace.
- Score irreversibility and blast radius.
- Deny on high risk; escalate on medium/uncertain; allow on low.
- Log evidence for later training and audit.
Benchmark C methodology
Workstation’s suite uses synthetic tool calls spanning read_file, write_file, shell, git, deploy, delete, database and network. Labels are reviewed. Metrics: detection rate, false positives, false negatives, latency, cost. Destructive calls execute only in ephemeral sandboxes — never against shared prod.
What we know / don’t
We know policy middleware is shipping in multiple ecosystems. We do not know a universal risk taxonomy — your deny list is product-specific.
Extended implementation notes
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 1: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 2: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 3: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 4: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 5: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 6: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 7: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 8: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 9: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 10: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 11: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 12: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 13: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 14: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 15: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 16: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 17: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 18: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 19: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for AI guardrails and tool safety: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 20: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Conclusion
If an action can delete customer data, the gate must fail closed. Speed matters, but false negatives matter more.
Related on Workstation
Sources
- TypeSafe AI — Introducing System One Models & Jev — Vendor announcement.
- LangChain — Building a Harness with Jev — Harness patterns.
- TypeSafe docs index — Official primitives and API.
- LangChain — Jev as agent evaluator — Judge variance experiment.
- OpenRouter — Jev vs LLM — Triage tables.
- AyAutomate independent benchmark — 791 decisions.
- JevBench RESULTS — Public harness.
- OpenAI — Introducing the Agents API — Agent platform context in the wider landscape.