Infrastructure d'entreprise pour l'entraînement et l'inférence IA à grande échelle
Les charges de travail d'IA modernes exigent une infrastructure conçue pour cet usage, capable d'évoluer d'une station de travail dotée d'un seul GPU jusqu'à des centaines de nœuds interconnectés. Workstation AI fournit les outils, les architectures et l'expertise pour concevoir, déployer et exploiter des clusters GPU orchestrés par Kubernetes, afin que vos équipes se concentrent sur le développement des modèles plutôt que sur la complexité de l'infrastructure.
GPU Cluster Architecture Overview
A well-designed GPU cluster combines high-performance compute nodes with fast interconnects, shared storage, and intelligent orchestration. Understanding the architecture is the foundation for building reliable AI infrastructure.
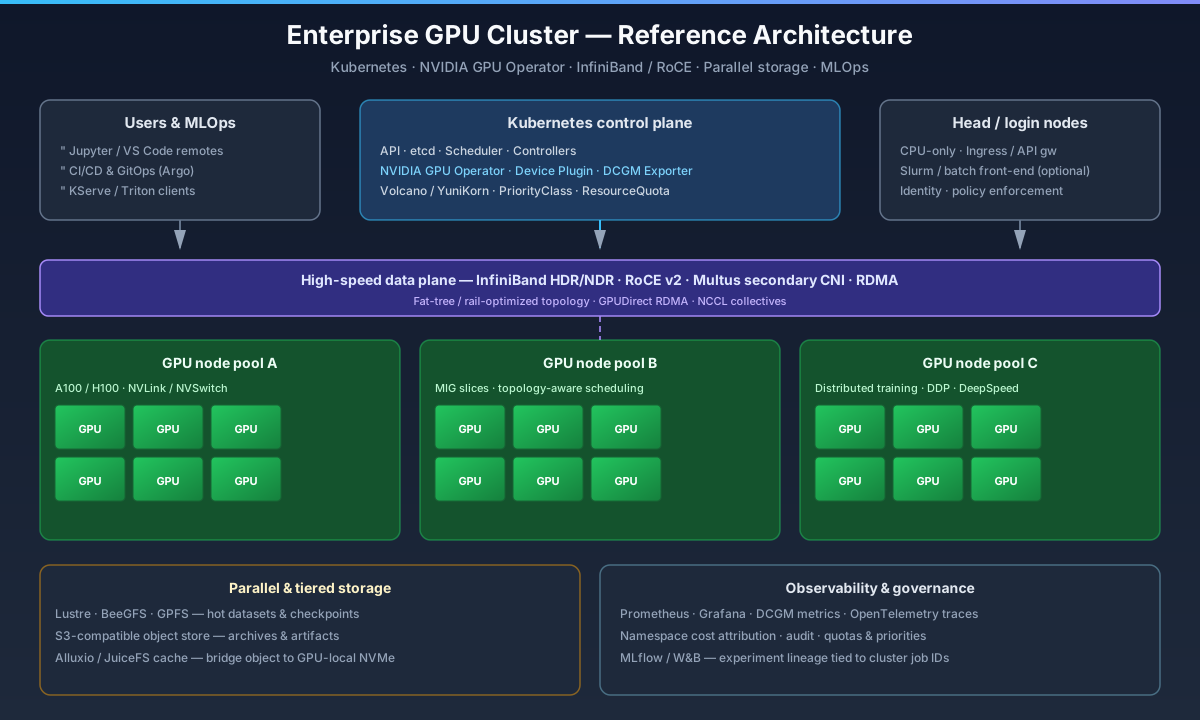
- Each compute node typically houses 4 to 8 GPUs (NVIDIA A100, H100, or L40S) connected via NVLink or NVSwitch for intra-node communication at up to 900 GB/s bandwidth.
- A dedicated management plane handles job scheduling, resource allocation, health monitoring, and user access control, keeping the data plane free for training traffic.
- Head nodes serve as the gateway for users to submit jobs, access Jupyter environments, and interact with MLOps tooling without consuming GPU resources.
- High-speed networking fabrics such as InfiniBand HDR (200 Gbps) or RoCE v2 connect nodes for distributed training, minimizing gradient synchronization latency.
- Shared parallel file systems (Lustre, GPFS, or BeeGFS) provide the throughput needed for large-scale dataset I/O without creating storage bottlenecks.
Kubernetes for AI Workloads
Kubernetes has become the de facto orchestrator for AI infrastructure, providing declarative resource management, automated scaling, and a rich ecosystem of GPU-aware components.
- ✓The NVIDIA GPU Operator automates the deployment of GPU drivers, container toolkit, device plugins, and monitoring exporters across all nodes, eliminating manual driver management.
- ✓Kubernetes device plugins expose GPU resources to the scheduler, enabling fine-grained allocation such as requesting specific GPU models, MIG (Multi-Instance GPU) slices, or time-shared access.
- ✓Custom scheduling policies including bin-packing, topology-aware placement, and gang scheduling ensure multi-GPU jobs land on nodes with optimal interconnect topology.
- ✓Namespace-based resource quotas and priority classes let teams share a cluster while guaranteeing SLAs for production inference workloads over experimental training runs.
- ✓Integration with Volcano or Apache YuniKorn provides batch scheduling capabilities purpose-built for AI and HPC workloads, supporting fair-share queuing and job preemption.
MLOps Pipelines on GPU Clusters
An end-to-end MLOps pipeline transforms raw data into deployed models with full reproducibility, versioning, and observability at every stage.
- ✓Data ingestion and preprocessing pipelines run on CPU nodes using Apache Spark or Dask, feeding cleaned datasets into shared storage for GPU training stages.
- ✓Experiment tracking platforms like MLflow or Weights & Biases capture hyperparameters, metrics, and artifacts, enabling reproducible comparisons across hundreds of training runs.
- ✓Distributed training frameworks (PyTorch DDP, DeepSpeed, Horovod) coordinate gradient updates across multiple GPUs and nodes, with Kubernetes managing pod placement and lifecycle.
- ✓Model registries version trained models with metadata and lineage, integrating with CI/CD pipelines to automate validation, A/B testing, and canary deployments.
- ✓Inference serving with Triton Inference Server, vLLM, or KServe delivers low-latency predictions with dynamic batching, model ensembles, and automatic GPU scaling based on request load.
Networking for Distributed AI
Network performance is often the bottleneck in distributed training. Choosing the right fabric and configuration is critical for scaling efficiency.
- ✓InfiniBand HDR/NDR provides the lowest latency and highest bandwidth (200-400 Gbps per port) with RDMA, making it ideal for large-scale training across 64+ nodes.
- ✓RoCE v2 (RDMA over Converged Ethernet) offers a cost-effective alternative that runs over standard Ethernet switches while still supporting RDMA for reduced CPU overhead.
- ✓Network topology matters: fat-tree and rail-optimized designs minimize oversubscription, while NVIDIA's SHARP protocol offloads collective operations to the network switches themselves.
- ✓For Kubernetes environments, Multus CNI enables pods to attach to both the primary cluster network and a secondary high-speed RDMA network for training traffic.
- ✓Network isolation using SR-IOV virtual functions gives each training pod direct hardware access to the network adapter, bypassing the kernel stack for wire-speed performance.
Storage Solutions for AI Workloads
AI workloads have diverse storage needs: high-throughput parallel reads for training data, low-latency access for checkpoints, and durable object storage for datasets and artifacts.
- ✓NFS remains a practical choice for smaller clusters and shared home directories, though throughput limitations make it unsuitable as the primary training data store beyond a few nodes.
- ✓Ceph provides a unified storage platform offering block (RBD), file (CephFS), and object (RGW) interfaces, scaling horizontally to petabytes with built-in replication and erasure coding.
- ✓Longhorn, a lightweight Kubernetes-native storage solution, delivers replicated block storage ideal for model checkpoints and persistent volumes in smaller GPU clusters.
- ✓High-performance caching layers using Alluxio or JuiceFS can bridge the gap between slow object storage (S3-compatible) and the throughput requirements of GPU data loaders.
- ✓A tiered storage strategy is essential: fast NVMe SSDs on compute nodes for scratch and checkpoints, parallel file systems for active datasets, and cold object storage for archival.
Monitoring GPU Utilization
Visibility into GPU health and utilization is essential for maximizing return on infrastructure investment and identifying performance bottlenecks before they impact training runs.
- ✓DCGM (Data Center GPU Manager) Exporter collects over 50 GPU metrics including SM utilization, memory bandwidth, temperature, power draw, and ECC error counts for Prometheus scraping.
- ✓Grafana dashboards provide real-time and historical views of per-GPU, per-node, and per-job utilization, enabling teams to identify idle resources and right-size allocations.
- ✓Alerting on GPU memory utilization, thermal throttling, and Xid errors enables proactive maintenance, preventing hardware failures from interrupting multi-day training runs.
- ✓Integration with Kubernetes metrics (kube-state-metrics) correlates GPU utilization with pod scheduling decisions, helping administrators optimize bin-packing and node pool sizing.
- ✓Cost attribution by namespace or team using GPU-hours metrics enables chargeback models that incentivize efficient resource usage and justify infrastructure expansion.
Scaling from Workstation to Data Center
Choose the right scale for your AI ambitions. Each tier builds on the previous, and Workstation AI provides migration paths between them.
| Niveau | GPUs | Cas d'usage | Réseau | Stockage | Orchestration |
|---|---|---|---|---|---|
| Single Workstation | 1-2 GPUs | Prototyping, fine-tuning small models, inference development | PCIe / NVLink | Local NVMe SSD | Docker / Docker Compose |
| Small Cluster | 8-32 GPUs (2-4 nodes) | Model training up to 7B parameters, multi-model inference serving | 25-100 GbE / RoCE v2 | NFS / Longhorn | K3s / MicroK8s |
| Mid-Scale Cluster | 32-128 GPUs (4-16 nodes) | Training 7B-70B parameter models, production inference at scale | InfiniBand HDR 200G | Ceph / BeeGFS | Kubernetes + GPU Operator |
| Large-Scale Cluster | 128-1000+ GPUs (16-128 nodes) | Foundation model training, multi-tenant AI platform | InfiniBand NDR 400G | Lustre / GPFS + Object Storage | Kubernetes + Volcano + Slurm |
Pipeline MLOps de bout en bout
From data ingestion to model serving, a well-architected MLOps pipeline on Kubernetes automates every stage of the machine learning lifecycle.
Data Ingestion
Preprocessing
Distributed Training
Experiment Tracking
Model Registry
Inference Serving
Planifiez votre cluster GPU
Que vous partiez d'une seule station de travail ou que vous conceviez une plateforme d'entraînement IA à plusieurs nœuds, notre équipe peut vous aider à définir l'infrastructure adaptée à vos charges de travail et à votre budget.